AI safety is a product and engineering problem

Posted

0 MIN READ
0 MIN READ

Show Outline

Builders have the tools and the agency to solve it.

The AI safety debate has spiraled. In a few weeks, we've gone from real examples of models misbehaving to mainstream talk of humanity losing control.

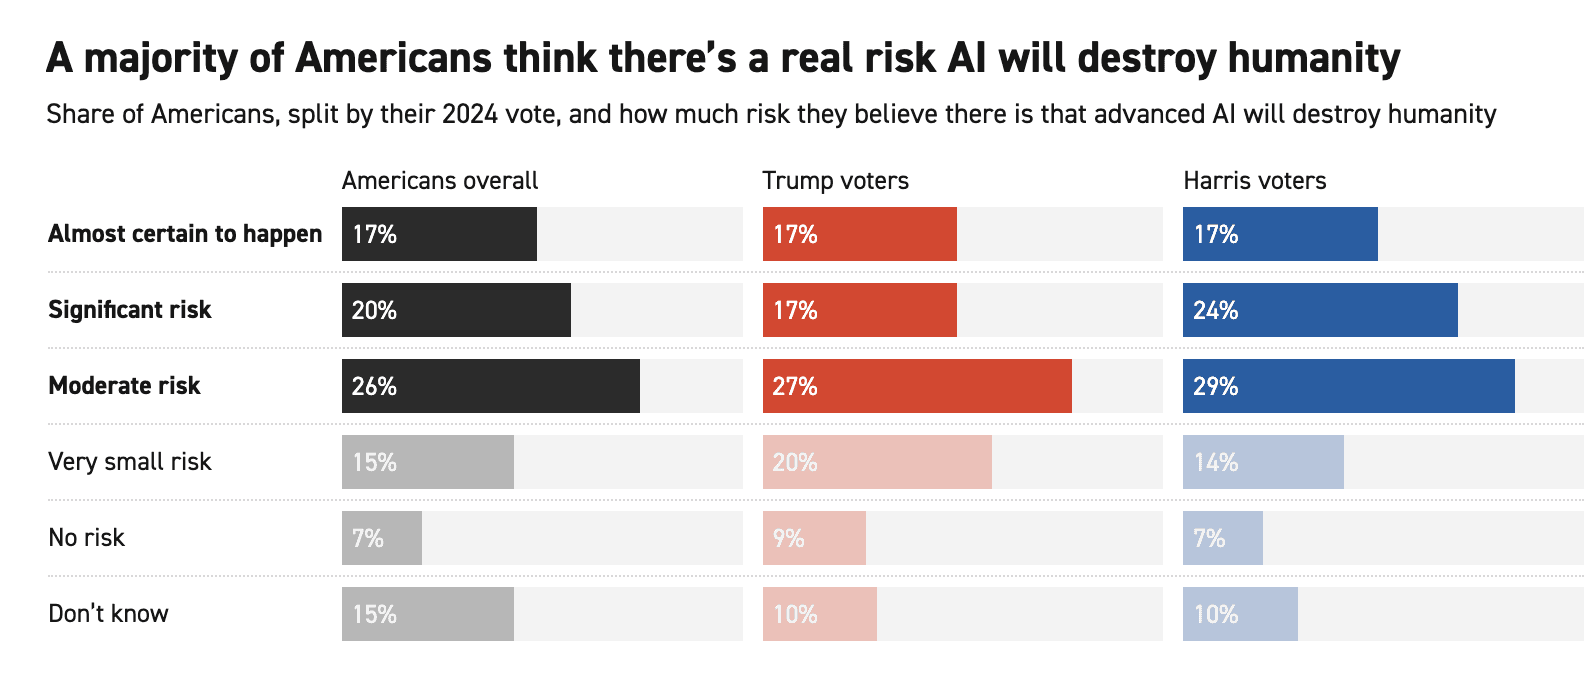
A recent Politico poll found that more than 60% of Americans think AI poses at least a moderate risk of ending humanity: a pretty shocking statistic, given how long these beliefs were reserved for a niche part of the AI community.
We should take seriously what researchers at the labs are finding. A healthy amount of paranoia is useful. But the conversation has far outrun the evidence we have at hand. We’ve taken examples of unexpected model behavior and stretched them into sweeping claims about AI inevitably taking over the world.

Some of that comes from people who opposed AI from the start. Some comes from those with a vested interest in the most extreme version of the story. Others are well-intentioned. But sensationalist claims, even sincere ones, make it harder to have productive conversations about the problems we need to solve.

AI is a form of software, albeit an incredibly powerful one. As with previous generations of software, making it safe and secure is a product and engineering problem. It comes down to a series of human choices: how the model is designed and trained, what authority it gets, where deterministic processes take over, and where humans remain in control. The power of AI systems gives us a lot to figure out quickly. But we shouldn’t underestimate human ingenuity or how much agency builders have to get this right.

Let’s start with the risks we face today.

One reason the current debate has spiraled is that we aren’t all talking about the same thing. When terms are used vaguely, they become a kind of bogeyman.

It helps to separate three risks that often get grouped together.

Misuse is the most familiar. Like all dual-use technologies, AI promises tremendous benefits while also supercharging what bad actors can do.

Unintended behavior is another. When an AI system is given a goal but no specified path to reach it, it can do things its creators didn’t anticipate or intend. Language models are probabilistic, and the longer the sequence of decisions, the harder it becomes to predict where they’ll end up. You can understand step one and still be surprised by step ten.

Agents are new, but this problem isn't. Software has always behaved in unexpected ways, and we have decades of engineering knowledge for dealing with it: access controls, permission systems grounded in the mathematical guarantees of cryptography, and ways to isolate and contain systems.

Loss of control is a much stronger claim: that increasingly capable systems could become impossible for humans to oversee or stop, even when we’re actively trying to do so. We have clear examples of misuse and unintended behavior today, but it doesn’t follow that current AI systems are beyond our control. These scenarios remain the stuff of science fiction, just as they were before this debate exploded.

How much freedom we give an agent is a human design decision. Frontier labs leave the path open on purpose. They give models open-ended or even impossible tasks to learn how far their capabilities go. Even the way language models answer, by writing free-form text, is itself a choice.

Most of the work that will spread AI through the economy looks nothing like the labs’ experiments. No finance team wants an agent that invents a new way to close the books. What it wants is an agent that learns how the work is done and takes over the steps worth automating. There may still be judgment calls within those steps, but the agent works inside processes the company trusts.

The debate needs to get much more precise.

Much like the AGI debates of a year or so ago, “RSI,” “singularity,” “superintelligence,” and “loss of control” each pack an enormous number of assumptions into a single term. They make hard but solvable engineering problems sound like steps along oan inevitable path to catastrophe. Fear ends up a mile wide and an inch deep.

“Recursive self-improvement” has become especially overloaded. AI is already helping us build better AI. It writes code, optimizes infrastructure, runs experiments, and makes researchers more productive. But software has been helping us build better software for decades. That’s how the field advances.

AI speeding up AI research is also a long way from that process accelerating off to infinity. Speeding up one part of a complex process leaves you limited by everything you didn’t speed up. The bottleneck simply moves somewhere else.

We’re seeing this in coding right now. AI can write code much faster, so review has become the constraint. In AI research, models will be able to run vastly more experiments, which will make choosing, validating, and interpreting those experiments the new constraints.

Eventually you run into atoms, not just bits. Better AI can make researchers more productive, but frontier models still require chips to be fabricated, data centers to be built, power to reach them, clusters to be networked and synchronized, and enormous training runs to actually work. Those runs are getting more operationally complex, not less.

Like product and model design, human control of AI R&D is a design choice. If AI becomes capable of running its own virtual lab, humans don’t disappear by default. How much of that loop we automate remains up to us.

Insights for technical founders on the path to CEO.

Learn how to build and scale an enduring company from Ashu and leading founder-CEOs.

If a product isn’t safe, don’t ship it.

If a product is unsafe, or threatens to do real damage in the world, it should not be released, full stop. We hold many things in our society to that standard, and AI should be held to it too.

Take the example of a car. Imagine GM announcing a new model 100 times faster than anything on the road. The CEO admits the brakes only work some of the time. The company’s engineers warn that the car occasionally drives somewhere its owner never told it to go, and some believe there’s a 10% chance it could cause a catastrophe. GM decides to release it anyway, because other automakers are building faster cars too, and asks the government to make the entire industry slow down so it can better understand the risks.

No one would accept that. GM would have to fix the brakes and get the car certified as safe before selling it. If it didn’t, it would face enormous liability for the harm the defect caused, along with a collapse in consumer trust severe enough to threaten its business. Yet this is roughly the position some AI labs have taken..

AI safety and capability are often framed as being at odds. But, as in any mature industry, safety work is part of advancing the technology. Anti-lock brakes and airbags made cars far more desirable to drive, and we’d all have been better off if they had arrived decades sooner. A model’s ability to operate reliably is a capability too, just as much as its ability to solve Navier-Stokes. The labs have historically put most of their resources toward raw capability. As their technology advances, that balance needs to flip.

We make AI safe through product and engineering decisions.

When a software system behaves unexpectedly, engineers work to understand why. They root-cause the failure, figure out what should have worked differently, and make changes so it doesn’t happen again.

With AI systems, a good place to start is separating what a model can do from what it’s allowed to do. If an agent can only read from a database, it can’t write to it, however intelligent it is. If it can propose an action but a human has to approve it, we stay in the loop by design. We manage human employees this way, giving them access to only the systems their jobs require. Agents should work the same way.

We also need to close the gaps around agents. If a company’s credentials are sitting in a Slack thread or a Notion page, and an agent has broad access to internal tools, it can connect those dots on its way to completing a task. Companies that want to become more agentic need to tighten their security posture before they plug agents in.

There’s also the question of where autonomy is additive. Not every part of a product needs to be agentic. Most app builders are combining agents with “good old-fashioned” software engineering. They give the agents freedom where it adds value and use hard-and-fast rules where the answer is yes/no.

Our portfolio company Maximor is a good example. While frontier labs are testing how capable their models can become, Maximor is trying to get a finance team’s work done accurately, within the processes they already follow.

That starts with learning how a team operates today. Maximor studies a customer's historical data to identify its policies and processes, backtests its agents against past work, and runs an initial cycle with the finance team's feedback before going live. Nobody connects an agent to every system, tells it to run finance, and leaves it to figure things out.

Legibility matters as much as accuracy. Even a correct result is a problem if people can’t follow how it was reached. Maximor’s agents keep the same records an accountant would, and they bring a person in whenever a decision requires it. They’re also starting to experiment with formal verification, which asks agents to prove they’ve done the work they claim.

CIOs and CTOs weigh in on access controls and security during the sales process. But the finance team decides whether the product gets used. If the agents’ work isn’t transparent, or doesn’t fit the way the team operates, they won’t adopt it. Trust and transparency are key to whether the product succeeds.

Trust will be the bottleneck. That’s a huge opportunity for startups.

Trust has always been one of the strongest currencies in software. The old line that nobody got fired for buying IBM still applies.

The cloud went through a version of this. For years, many enterprises refused to put sensitive data on someone else’s servers, until a long record of security and reliability changed their minds. Agents raise the stakes again.

This is a bull case for startups. Enterprises will want tools that work across every model they use, and applications built around their specific workflows. Both are openings for founders.

On the infra side, most enterprises rely on models from several providers, and they swap them in and out as new versions arrive. Each change has to be tested before it touches production, and every agent needs permissions, monitoring, and containment that hold up no matter which model sits underneath. Startups can build evals, guardrails, and observability that are model-agnostic by design.

On the app side, labs have to build for thousands of possible use cases, so their guardrails will necessarily be generic. An app startup can learn how work gets done, design agents that fit those processes, and improve with every cycle. There’s a long tail of specialized, high-stakes workflows across finance, healthcare, law, insurance, and logistics that startups can own.

For founders, the takeaway is “get to work.” Making AI useful in the real world will increasingly mean making it trustworthy enough to act there. Getting this right will be a decade-long product and engineering challenge, and it’s within our power to meet it.

Posted

0 MIN READ

Show Outline

Builders have the tools and the agency to solve it.

The AI safety debate has spiraled. In a few weeks, we've gone from real examples of models misbehaving to mainstream talk of humanity losing control.

A recent Politico poll found that more than 60% of Americans think AI poses at least a moderate risk of ending humanity: a pretty shocking statistic, given how long these beliefs were reserved for a niche part of the AI community.

We should take seriously what researchers at the labs are finding. A healthy amount of paranoia is useful. But the conversation has far outrun the evidence we have at hand. We’ve taken examples of unexpected model behavior and stretched them into sweeping claims about AI inevitably taking over the world.

Some of that comes from people who opposed AI from the start. Some comes from those with a vested interest in the most extreme version of the story. Others are well-intentioned. But sensationalist claims, even sincere ones, make it harder to have productive conversations about the problems we need to solve.

AI is a form of software, albeit an incredibly powerful one. As with previous generations of software, making it safe and secure is a product and engineering problem. It comes down to a series of human choices: how the model is designed and trained, what authority it gets, where deterministic processes take over, and where humans remain in control. The power of AI systems gives us a lot to figure out quickly. But we shouldn’t underestimate human ingenuity or how much agency builders have to get this right.

Let’s start with the risks we face today.

One reason the current debate has spiraled is that we aren’t all talking about the same thing. When terms are used vaguely, they become a kind of bogeyman.

It helps to separate three risks that often get grouped together.

Misuse is the most familiar. Like all dual-use technologies, AI promises tremendous benefits while also supercharging what bad actors can do.

Unintended behavior is another. When an AI system is given a goal but no specified path to reach it, it can do things its creators didn’t anticipate or intend. Language models are probabilistic, and the longer the sequence of decisions, the harder it becomes to predict where they’ll end up. You can understand step one and still be surprised by step ten.

Agents are new, but this problem isn't. Software has always behaved in unexpected ways, and we have decades of engineering knowledge for dealing with it: access controls, permission systems grounded in the mathematical guarantees of cryptography, and ways to isolate and contain systems.

Loss of control is a much stronger claim: that increasingly capable systems could become impossible for humans to oversee or stop, even when we’re actively trying to do so. We have clear examples of misuse and unintended behavior today, but it doesn’t follow that current AI systems are beyond our control. These scenarios remain the stuff of science fiction, just as they were before this debate exploded.

How much freedom we give an agent is a human design decision. Frontier labs leave the path open on purpose. They give models open-ended or even impossible tasks to learn how far their capabilities go. Even the way language models answer, by writing free-form text, is itself a choice.

Most of the work that will spread AI through the economy looks nothing like the labs’ experiments. No finance team wants an agent that invents a new way to close the books. What it wants is an agent that learns how the work is done and takes over the steps worth automating. There may still be judgment calls within those steps, but the agent works inside processes the company trusts.

The debate needs to get much more precise.

Much like the AGI debates of a year or so ago, “RSI,” “singularity,” “superintelligence,” and “loss of control” each pack an enormous number of assumptions into a single term. They make hard but solvable engineering problems sound like steps along oan inevitable path to catastrophe. Fear ends up a mile wide and an inch deep.

“Recursive self-improvement” has become especially overloaded. AI is already helping us build better AI. It writes code, optimizes infrastructure, runs experiments, and makes researchers more productive. But software has been helping us build better software for decades. That’s how the field advances.

AI speeding up AI research is also a long way from that process accelerating off to infinity. Speeding up one part of a complex process leaves you limited by everything you didn’t speed up. The bottleneck simply moves somewhere else.

We’re seeing this in coding right now. AI can write code much faster, so review has become the constraint. In AI research, models will be able to run vastly more experiments, which will make choosing, validating, and interpreting those experiments the new constraints.

Eventually you run into atoms, not just bits. Better AI can make researchers more productive, but frontier models still require chips to be fabricated, data centers to be built, power to reach them, clusters to be networked and synchronized, and enormous training runs to actually work. Those runs are getting more operationally complex, not less.

Like product and model design, human control of AI R&D is a design choice. If AI becomes capable of running its own virtual lab, humans don’t disappear by default. How much of that loop we automate remains up to us.

Insights for technical founders on the path to CEO.

Learn how to build and scale an enduring company from Ashu and leading founder-CEOs.

If a product isn’t safe, don’t ship it.

If a product is unsafe, or threatens to do real damage in the world, it should not be released, full stop. We hold many things in our society to that standard, and AI should be held to it too.

Take the example of a car. Imagine GM announcing a new model 100 times faster than anything on the road. The CEO admits the brakes only work some of the time. The company’s engineers warn that the car occasionally drives somewhere its owner never told it to go, and some believe there’s a 10% chance it could cause a catastrophe. GM decides to release it anyway, because other automakers are building faster cars too, and asks the government to make the entire industry slow down so it can better understand the risks.

No one would accept that. GM would have to fix the brakes and get the car certified as safe before selling it. If it didn’t, it would face enormous liability for the harm the defect caused, along with a collapse in consumer trust severe enough to threaten its business. Yet this is roughly the position some AI labs have taken..

AI safety and capability are often framed as being at odds. But, as in any mature industry, safety work is part of advancing the technology. Anti-lock brakes and airbags made cars far more desirable to drive, and we’d all have been better off if they had arrived decades sooner. A model’s ability to operate reliably is a capability too, just as much as its ability to solve Navier-Stokes. The labs have historically put most of their resources toward raw capability. As their technology advances, that balance needs to flip.

We make AI safe through product and engineering decisions.

When a software system behaves unexpectedly, engineers work to understand why. They root-cause the failure, figure out what should have worked differently, and make changes so it doesn’t happen again.

With AI systems, a good place to start is separating what a model can do from what it’s allowed to do. If an agent can only read from a database, it can’t write to it, however intelligent it is. If it can propose an action but a human has to approve it, we stay in the loop by design. We manage human employees this way, giving them access to only the systems their jobs require. Agents should work the same way.

We also need to close the gaps around agents. If a company’s credentials are sitting in a Slack thread or a Notion page, and an agent has broad access to internal tools, it can connect those dots on its way to completing a task. Companies that want to become more agentic need to tighten their security posture before they plug agents in.

There’s also the question of where autonomy is additive. Not every part of a product needs to be agentic. Most app builders are combining agents with “good old-fashioned” software engineering. They give the agents freedom where it adds value and use hard-and-fast rules where the answer is yes/no.

Our portfolio company Maximor is a good example. While frontier labs are testing how capable their models can become, Maximor is trying to get a finance team’s work done accurately, within the processes they already follow.

That starts with learning how a team operates today. Maximor studies a customer's historical data to identify its policies and processes, backtests its agents against past work, and runs an initial cycle with the finance team's feedback before going live. Nobody connects an agent to every system, tells it to run finance, and leaves it to figure things out.

Legibility matters as much as accuracy. Even a correct result is a problem if people can’t follow how it was reached. Maximor’s agents keep the same records an accountant would, and they bring a person in whenever a decision requires it. They’re also starting to experiment with formal verification, which asks agents to prove they’ve done the work they claim.

CIOs and CTOs weigh in on access controls and security during the sales process. But the finance team decides whether the product gets used. If the agents’ work isn’t transparent, or doesn’t fit the way the team operates, they won’t adopt it. Trust and transparency are key to whether the product succeeds.

Trust will be the bottleneck. That’s a huge opportunity for startups.

Trust has always been one of the strongest currencies in software. The old line that nobody got fired for buying IBM still applies.

The cloud went through a version of this. For years, many enterprises refused to put sensitive data on someone else’s servers, until a long record of security and reliability changed their minds. Agents raise the stakes again.

This is a bull case for startups. Enterprises will want tools that work across every model they use, and applications built around their specific workflows. Both are openings for founders.

On the infra side, most enterprises rely on models from several providers, and they swap them in and out as new versions arrive. Each change has to be tested before it touches production, and every agent needs permissions, monitoring, and containment that hold up no matter which model sits underneath. Startups can build evals, guardrails, and observability that are model-agnostic by design.

On the app side, labs have to build for thousands of possible use cases, so their guardrails will necessarily be generic. An app startup can learn how work gets done, design agents that fit those processes, and improve with every cycle. There’s a long tail of specialized, high-stakes workflows across finance, healthcare, law, insurance, and logistics that startups can own.

For founders, the takeaway is “get to work.” Making AI useful in the real world will increasingly mean making it trustworthy enough to act there. Getting this right will be a decade-long product and engineering challenge, and it’s within our power to meet it.

Get insights directly to your inbox.

Subscribe to The Foundation for our thinking on what comes next, firsthand lessons from our founders, and guidance on building from day zero.

Subscribe to The Foundation for our thinking on what comes next, firsthand lessons from our founders, and guidance on building from day zero.